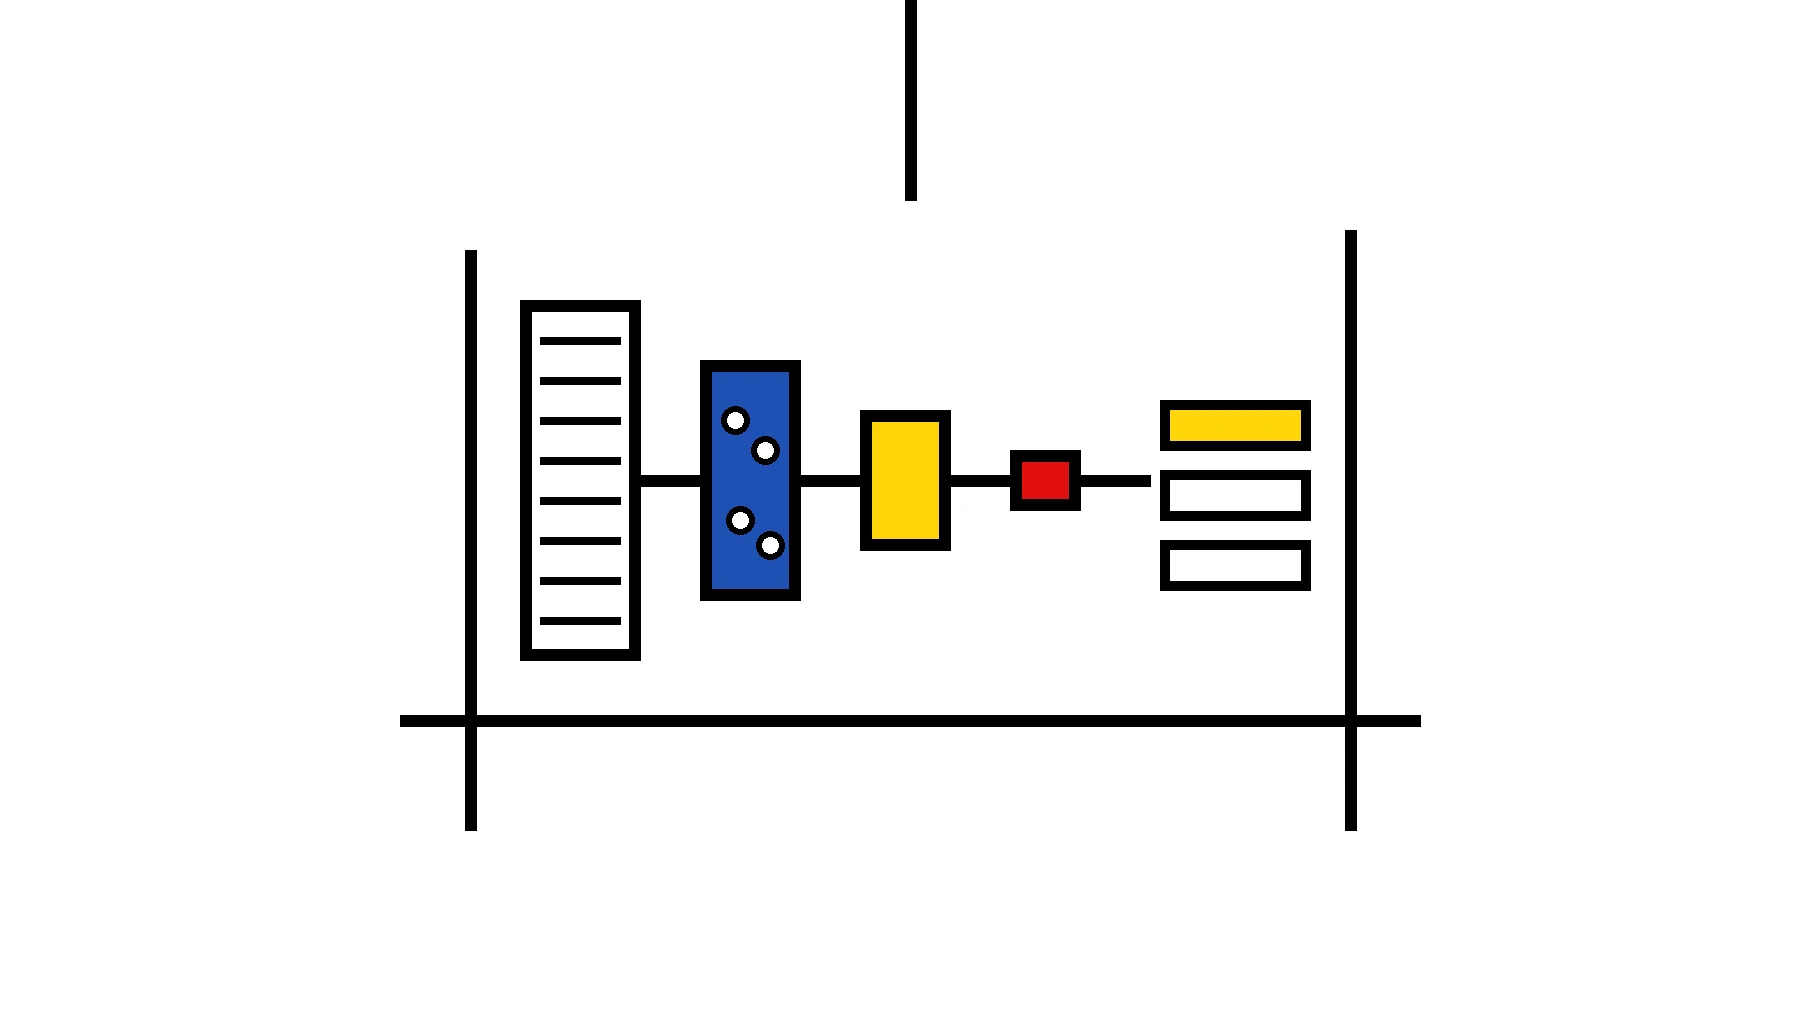
"AI matching" sounds like magic. It's a pipeline.
Pipelines we understand. We've been paged by enough of them.
How does a job matching algorithm find your best-fit role? It turns your CV and each vacancy into structured data, removes duplicate listings, drops roles that fail your hard constraints, and ranks the rest by how close the meaning of your skills is to what the role needs. Your job title is one input. What you did is the main one.
TL;DR
- Four steps: parse, deduplicate, filter, rank. Each one can fail on its own.
- Embeddings compare meaning, not words. "Built UI components" lands near "frontend development" without a shared keyword.
- It breaks in known places: career changers, niche roles, biased history.
- Write what you did, not what you were called. The algorithm can only match what's in the text.
Step 1: Parse the prose into fields
Parsing turns text into fields a computer can compare.
A vacancy becomes a normalised title, seniority, required and nice-to-have skills, company type, work model and salary. Salary is the field most often missing: in our March–September 2026 data from the Netherlands and Australia, only 4,631 of 57,486 postings (8%) quoted pay.
Your CV gets the same treatment. "Ran quarterly reporting in SQL for finance" becomes SQL, reporting, recurring cadence, finance stakeholders.
Everything downstream depends on this step. Garbage in, confidently ranked garbage out.
Step 2: Count each job once
Deduplication groups the copies of one vacancy into one job.
The employer posts it. Three agencies repost it, each with a new intro. A naive system ranks all four, and your top ten is the same job in four hats.
SlashHash turns each posting into an embedding: a list of numbers that captures what the text means. Postings that sit close together are one job. Rewording the intro doesn't change the meaning, so it doesn't fool the clustering.
Step 3: Filter on what you won't bend on
Hard constraints remove roles before anything gets ranked.
Visa sponsorship, a salary floor, remote only, a maximum commute. A role that fails one isn't a weak match. It's no match. Scoring it 74% is a polite way of wasting your evening. (Our piece on personalized recommendations goes deeper on constraints versus preferences.)
Step 4: How the job matching algorithm ranks
Ranking sorts what's left by how close your skills are to the role's, in meaning.
Matching has had three generations:
- Keywords. Does "project management" appear in both? Write "coordinated delivery timelines" and you're out.
- Skill lists. Both sides map to a fixed list, so synonyms meet. Only as current as whoever maintains the list.
- Embeddings. Text lands in a space where similar meanings sit close. Models like Sentence-BERT made this cheap enough to run on every sentence.
The third generation is why "kept production running and fixed it at 3 a.m." can find an SRE role. LinkedIn's engineers describe running this at scale in Learning to Retrieve for Job Matching (2024).
Here's the catch: the algorithm doesn't know what you did. It knows what you wrote.
Where matching breaks
Every system has failure modes. These are the ones that bite job seekers.
- The career changer. Your CV speaks your old field's language, so the matcher keeps serving you the past. Like a cache that never expires: fast, confident, stale.
- Niche roles. Few examples means noisy similarity. Treat matches as hints.
- Biased history. A model trained on past hires can repeat past exclusions. That's why the EU AI Act lists candidate screening as high-risk, and why GDPR article 22 lets you refuse a purely automated rejection.
- The bare percentage. "87%" without a reason can't be checked, so it can't be fixed.
A score should shorten your list. It shouldn't make your decisions.
What it means for your CV
You can't change the algorithm. You can change its input.
- Name skills and tools. "Forecasting in Excel and Power BI" gives three things to match. "Finance" gives one, vaguely.
- Show depth with results. "Cut month-end close from five days to three" beats "responsible for month-end".
- Keep your titles. Humans still read them. Just don't make them carry the story.
- Use the posting's words only for what's true. The interview runs the integration test.
SlashHash's CV Alignment (beta) does that last check per posting: where your wording matches, where a screener could miss real experience, where the gaps are. It doesn't invent experience.
FAQ
How does a job matching algorithm work? It parses CVs and vacancies into fields, groups duplicate listings, removes roles that fail your hard constraints, and ranks the rest by how close your skills are in meaning to what the role needs.
What is an embedding? A list of numbers that represents what a piece of text means. Similar meanings get similar numbers, so "built UI components" and "frontend development" end up close together.
Can it match me to a role with a different title? Yes, if it ranks on meaning rather than keywords, and if your CV describes what you actually did.
Are job matching algorithms biased? They can be, if they learn from biased hiring history. That's why the EU AI Act treats candidate screening as high-risk and GDPR article 22 limits purely automated rejections.
Your move this week
- Pick one vacancy you'd want whose title doesn't match yours.
- Write one line from your own work for each of its five core skills.
- Four or five lines? Apply with them. Two or fewer? You've found your skill gap, which is also data.
A match tells you that you could do the job. To work out whether you'd want it, read how to find the right job.
Figures: SlashHash analysis of 57,486 AI-related postings, March–September 2026, behind our AI career guides. Research: Reimers & Gurevych, Sentence-BERT (2019); Shen et al., Learning to Retrieve for Job Matching (2024). Law: EU AI Act, GDPR article 22.